Gemini 3.1 Flash-Lite – Intelligence at Scale With Speed & Cost Efficiency

Gemini 3.1 Flash-Lite is Google DeepMind's fastest, most cost-efficient model yet. It delivers enterprise-grade reasoning and understanding for the world's most demanding high-volume workloads.

Trusted by users from 10,000+ companies

Capabilities of Gemini 3.1 Flash-Lite

Gemini 3.1 Flash-Lite is built for production-grade scalability while maintaining multimodal flexibility and developer control.

Extended Context

Extended Context

Processes up to one million input tokens, enabling comprehensive long-document review and large-scale dataset analysis within a single streamlined request cycle.

Adaptive Reasoning

Adaptive Reasoning

Lets developers adjust reasoning depth dynamically, balancing response quality, processing speed, and operational cost for varied production requirements.

Rapid Throughput

Rapid Throughput

Delivers high token-per-second generation speeds, supporting responsive real-time applications and latency-sensitive production-grade AI deployments.

Frequently Asked Questions

Learn more about Gooogle's newest, fastest, and most, cost-effective model through other people's questions..

Structured Outputs

Structured Outputs

Generates JSON and schema-aligned responses, simplifying automation workflows and backend system integrations across enterprise environments.

Multimodal Intelligence

Multimodal Intelligence

Understands text, images, audio, video, and PDFs together, allowing unified cross-format reasoning and seamless multimodal workflow execution at scale.

Batch Processing

Batch Processing

Handles high-frequency API requests efficiently, maintaining predictable performance across large-scale, production-level workloads.

Low Latency

Low Latency

Optimized architecture ensures fast response times for interactive platforms, embedded systems, and customer-facing digital experiences.

Enterprise Deployment

Enterprise Deployment

Available through Google AI Studio and Vertex AI, supporting secure, scalable, and fully managed production implementations.

Safety Framework

Safety Framework

Inherits Gemini model safeguards, applying responsible AI controls, content filtering, and risk mitigation standards consistently.

Benchmarks That Break the Tier

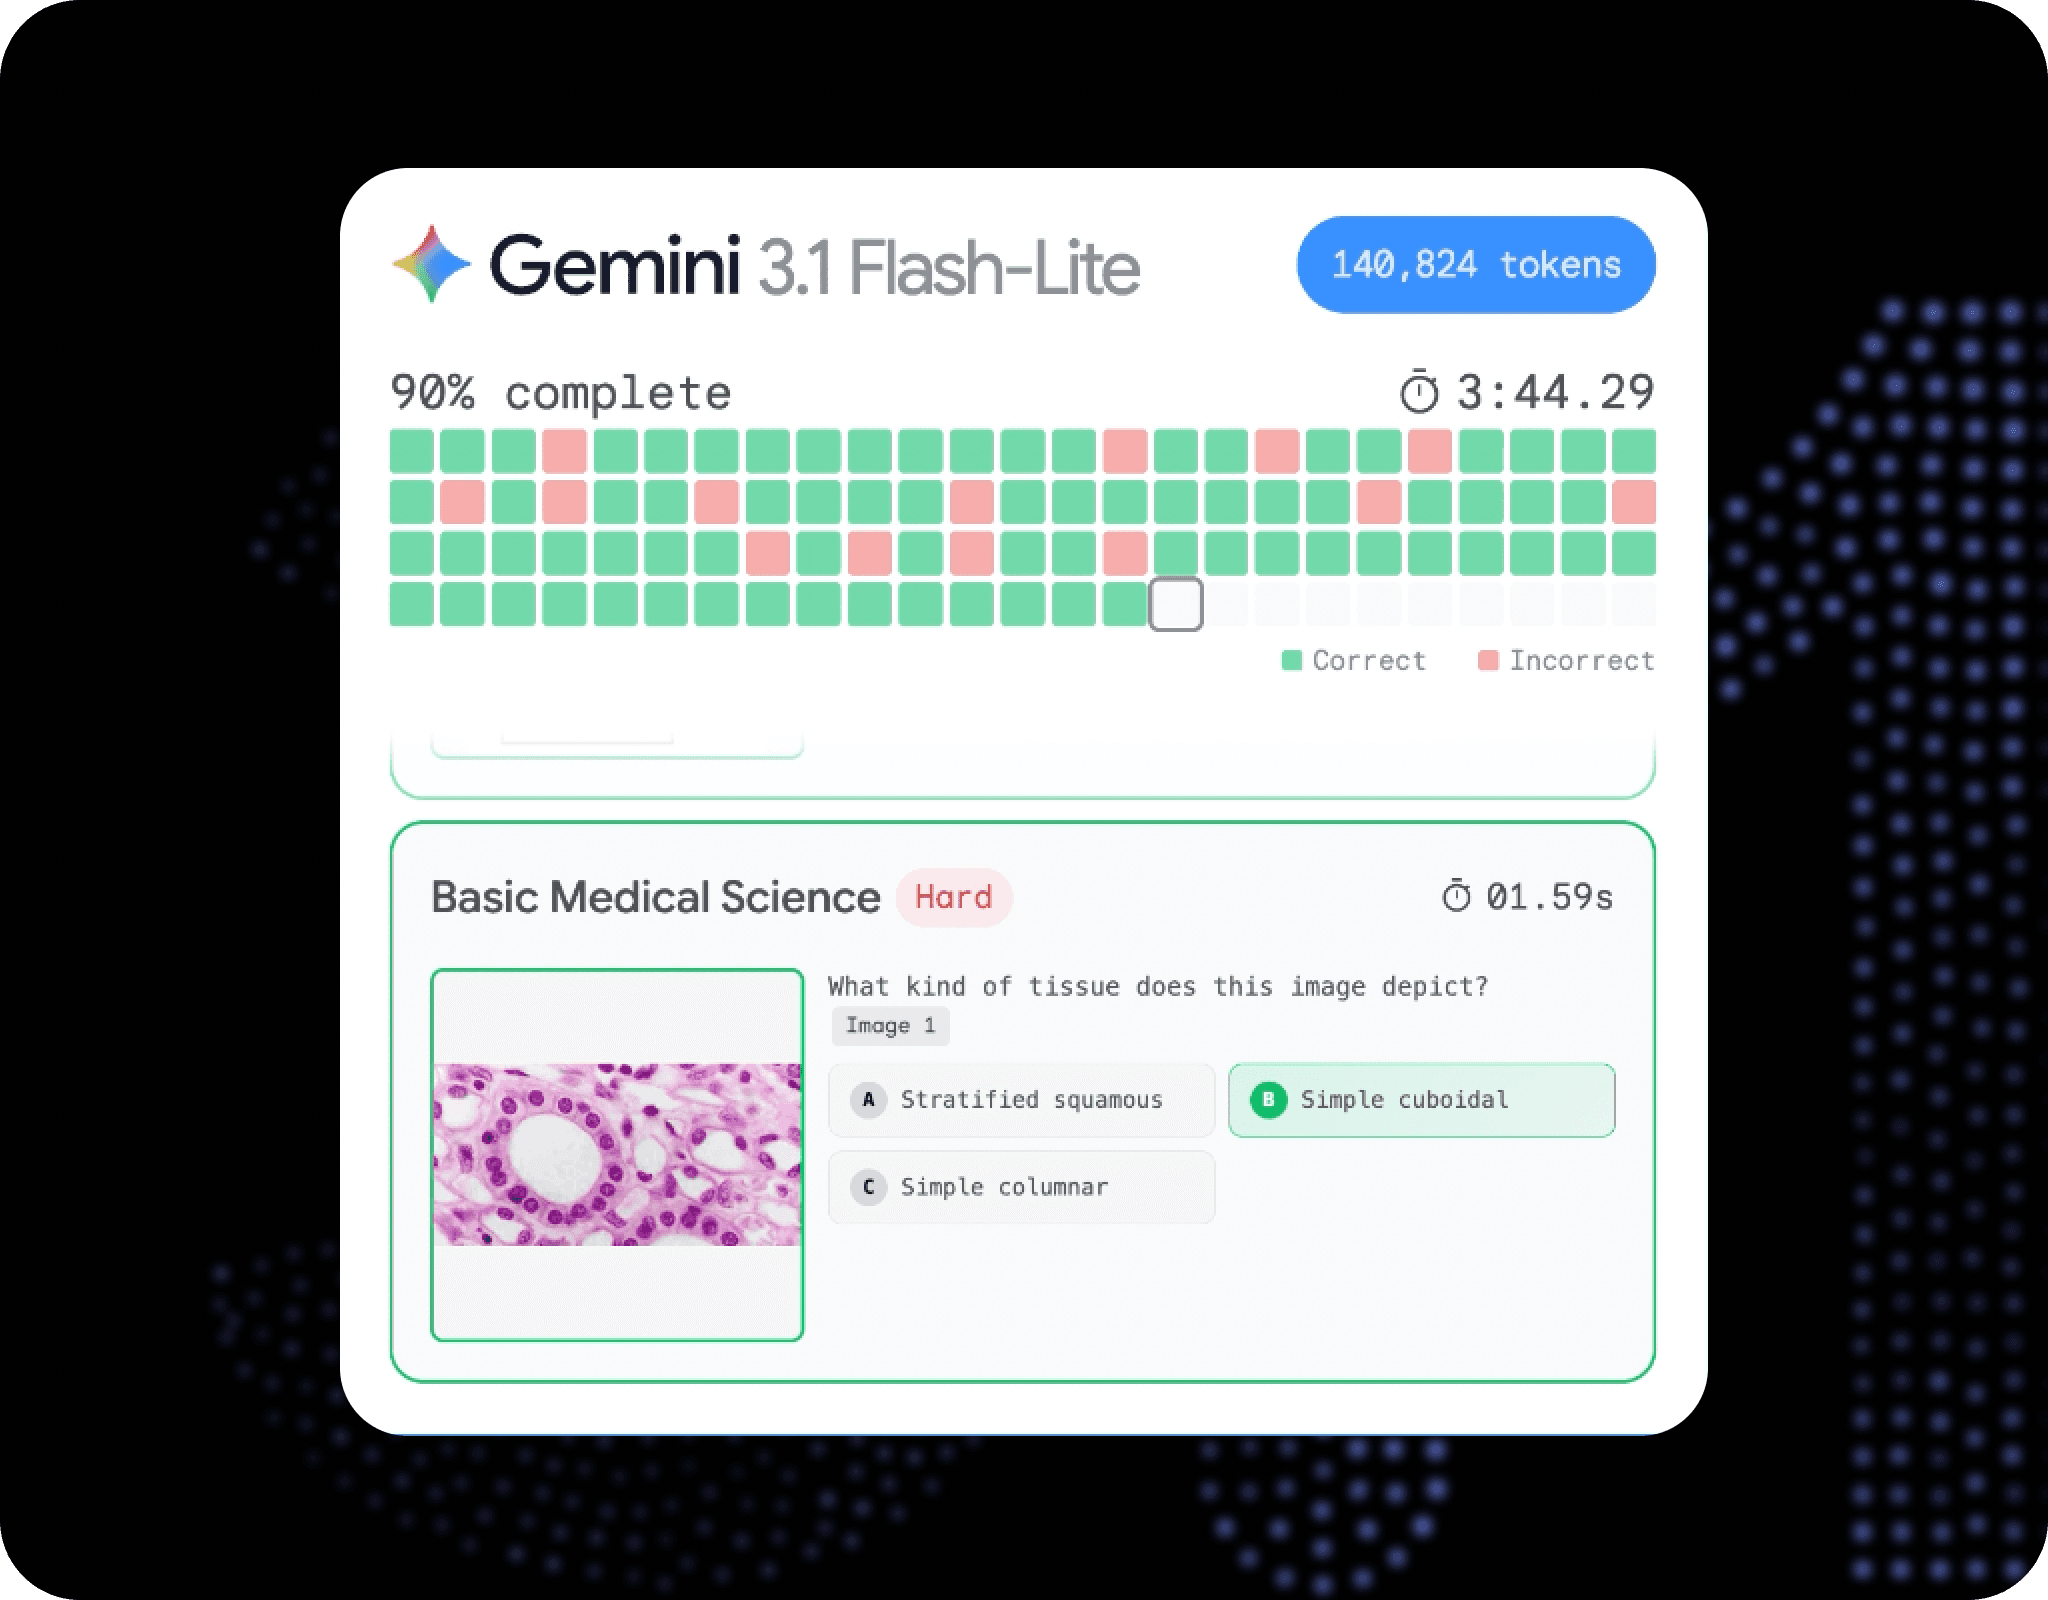
Gemini 3.1 Flash-Lite routinely outscores models from higher tiers and prior generations, proving that efficiency and intelligence are no longer a trade-off.

Blazing Output Speed

Blazing Output Speed

Up to 2.5× faster time-to-first-token and significantly higher token generation speeds compared to earlier Flash-Lite models, making it ideal for latency-sensitive workflows.

Cost-to-Performance Sweet Spot

Cost-to-Performance Sweet Spot

Optimized token pricing enables high-volume workloads like classification, moderation, and translation at scale without enterprise-level cost overhead.

Multimodal Excellence

Multimodal Excellence

Performs strongly across reasoning and multimodal benchmarks, demonstrating reliable knowledge retrieval, structured generation, and cross-format understanding.

Enterprise Productivity Automation

Integrate into productivity environments like Microsoft 365 or Google Workspace to automate document drafting, spreadsheet analysis, meeting summaries, and large-scale internal knowledge processing.

Enterprise Productivity Automation

High-Volume Content & Localization

Power bulk translation, moderation pipelines, and global content adaptation with low latency, predictable cost efficiency and seamless multilingual workflow automation across distributed systems.

High-Volume Content & Localization

Data Pipelines & Structured Output Systems

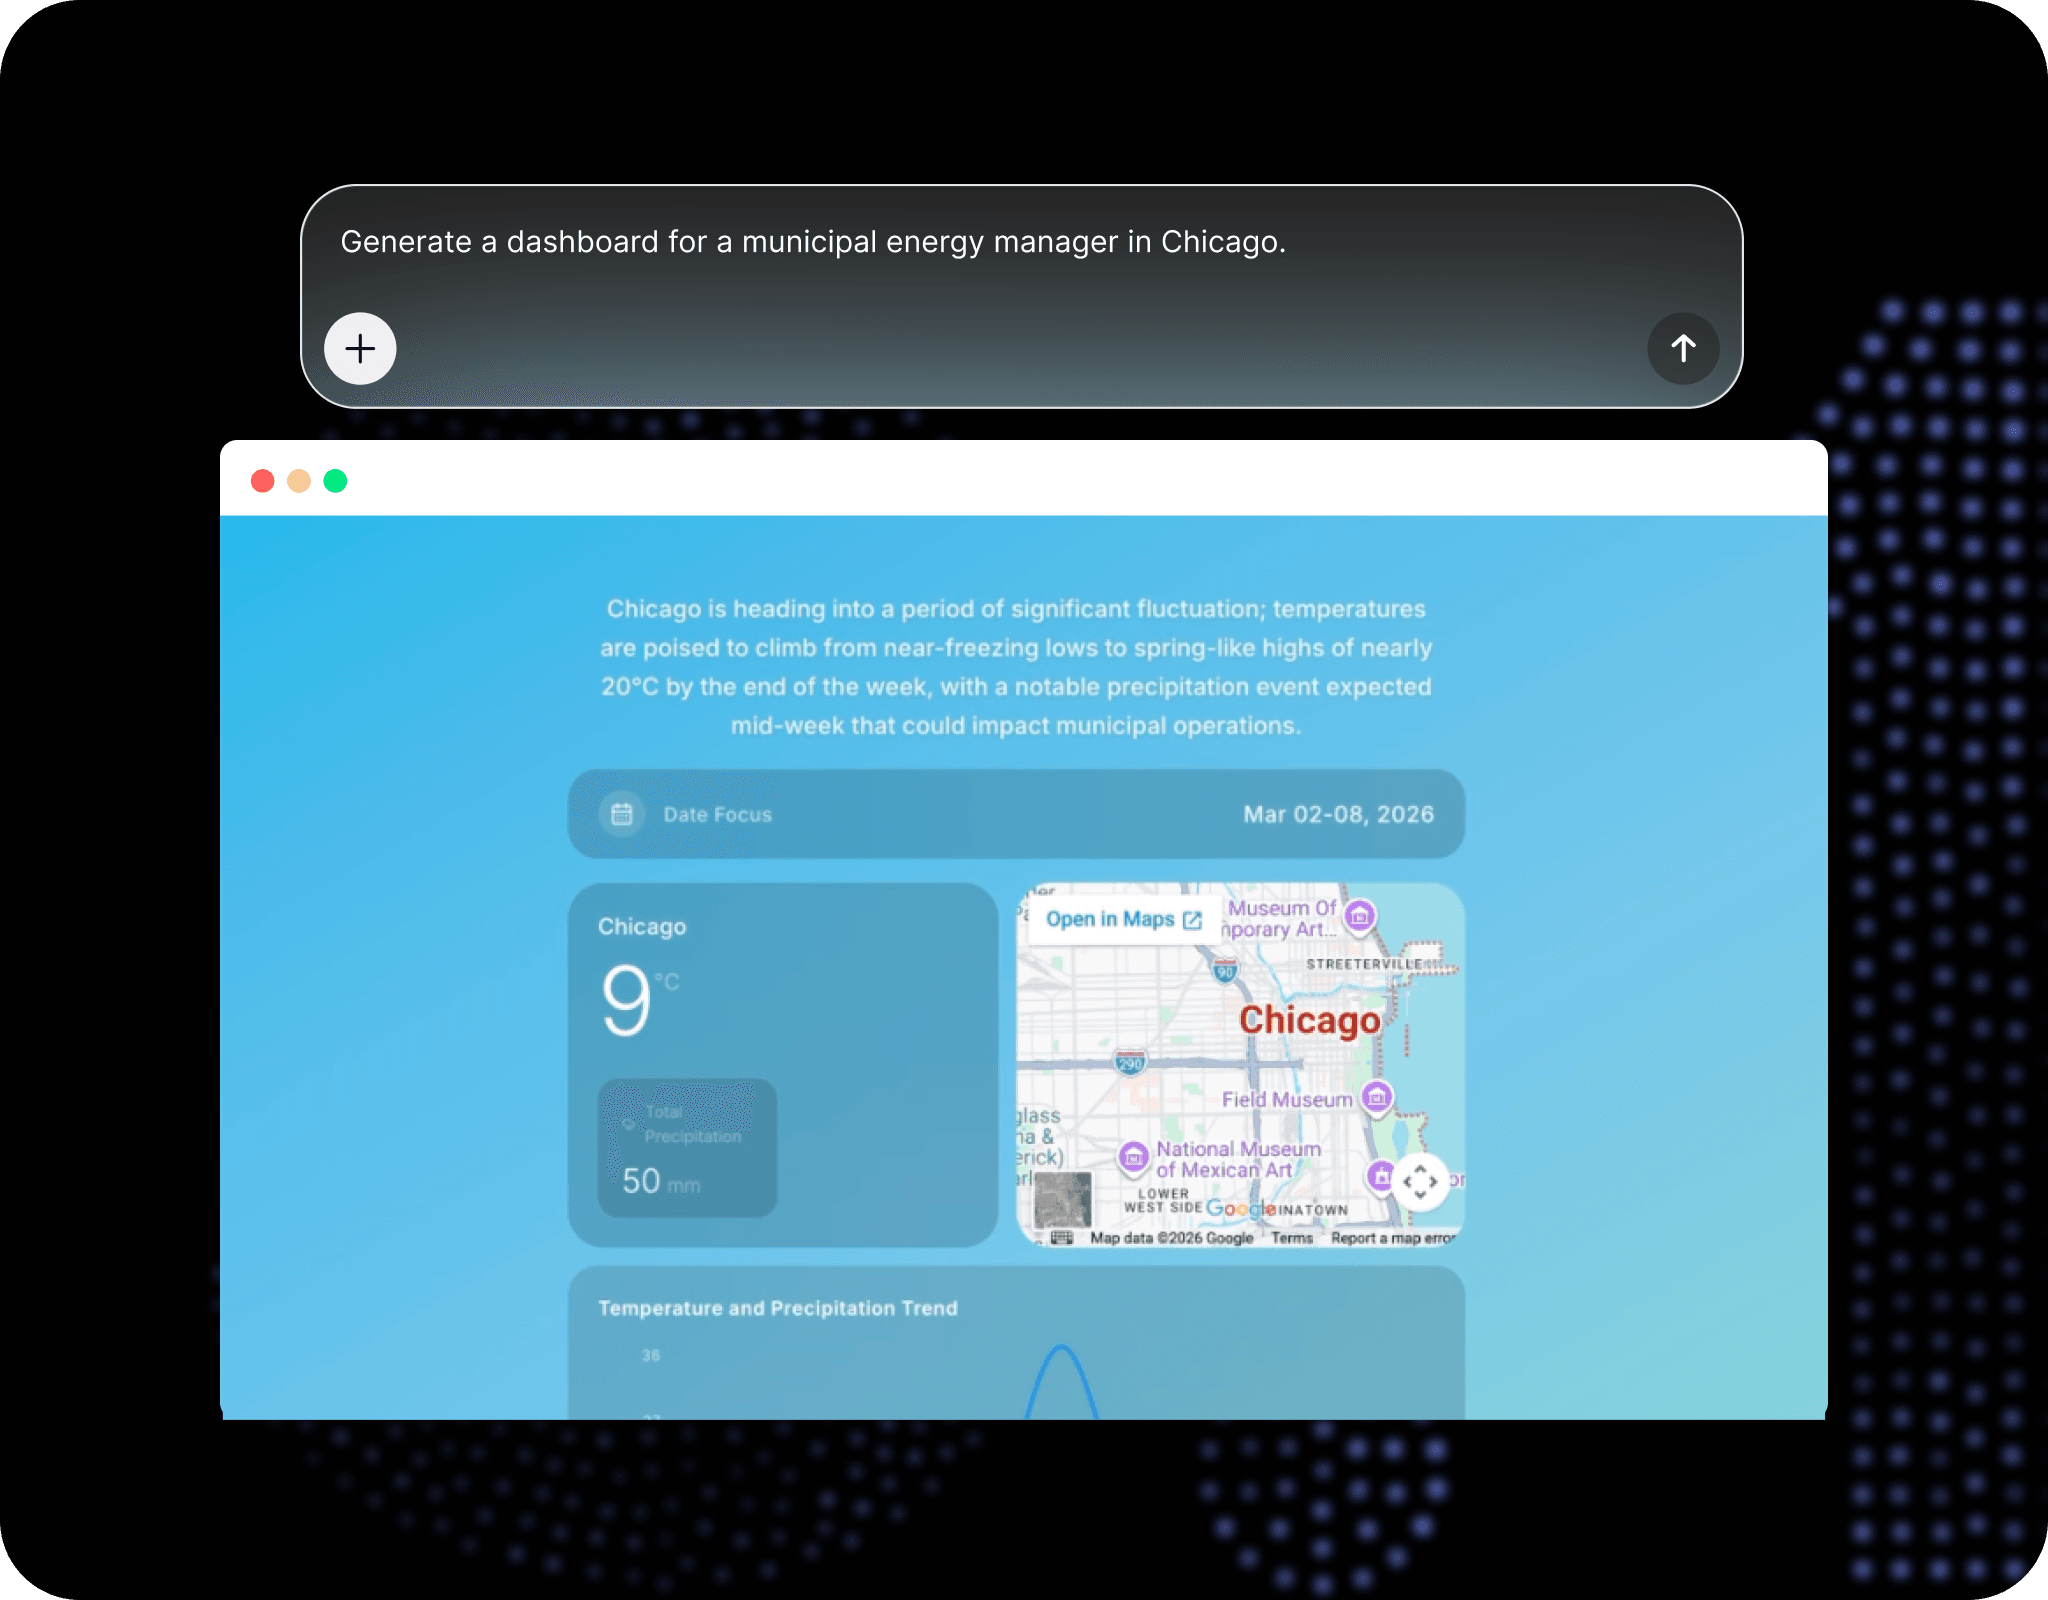
Deploy inside dashboards, SaaS platforms, and internal tools to extract structured data, classify inputs, and generate reports in real time via API integrations such as Vertex AI.

Data Pipelines & Structured Output Systems